The Benefit of Information Hiding
The general principle: If you expose more information than you need to, things will change more than they need to. And every single time things change you’re opening yourself up to the possibility of things breaking, while also incurring an additional maintenance cost.
A simple example
We had a table of reports. Each row showed a report’s name, and a Download button — but only for reports that could actually be downloaded.
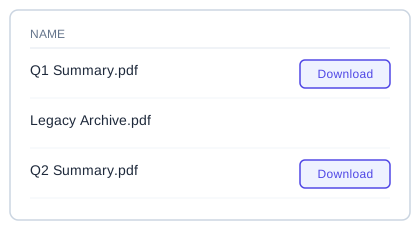
The reports came from a service:
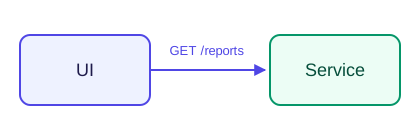
GET /reports

[
  { "id": "1", "name": "Q1 Summary.pdf", "storageType": "s3" },
  { "id": "2", "name": "Legacy Archive.pdf", "storageType": "backblaze_b2" }
]
Three of the four storage types supported direct downloads (all except backblaze_b2). So the check looked like this inside each table row:
const canDownload =
  report.storageType === "s3" ||
  report.storageType === "gcs" ||
  report.storageType === "azure_blob";

{
  canDownload && <DownloadButton />;
}
It worked.
Then the backend added support for a new storage provider, cloudflare_r2 — and unlike backblaze_b2, this one did support direct downloads.
{ "id": "3", "name": "Q2 Summary.pdf", "storageType": "cloudflare_r2" }However, nobody updated canDownload in the UI when this new storage provider was added. Reports stored on cloudflare_r2 silently rendered with no Download button, even though they were fully downloadable.
Customers started complaining.
Whose fault was it?
Maybe QA should have caught this bug. Maybe a UI developer should have spoken up in a meeting when they heard the backend team was adding this new storage type. Maybe a PM should have directly looped in a UI developer when scoping this feature.
But the real blame lies in the design of this feature from the start, in my opinion. Had the backend never exposed storageType to the UI to begin with, we probably would have never seen this bug.
The fix
What if the API exposed something like isDownloadable instead of storageType?
{ "id": "3", "name": "Q2 Summary.pdf", "isDownloadable": true }{
report.isDownloadable && <DownloadButton />;
}That would be exposing much less information to the UI — but the UI would still be able to render the Download button correctly.
The UI wouldn’t know anything about any of the storage types, which would mean that if anything associated with storage types changed (a storage provider was added, deleted, or changed), the UI wouldn’t have to change.
There would be no way for the UI to introduce a bug due to a storage provider change. It’s true that the backend could still introduce a similar bug (by not returning the correct value of isDownloadable in the API), but the risk of that happening is smaller.
Compare this to the previous approach where the API was using storageType. If a storageType changed, that would trigger a change in the UI to update canDownload. So every time a storageType changed, there would be another service (the UI) that had to change, rebuild, and be re-deployed. There’s not just more risk of bugs with this approach, but there is also an increased maintainability cost.
Takeaway
Storage types were just the example — the pattern is more general: anything you expose across a service boundary is something a consumer can end up depending on, and anything depended on is something that can eventually change and cause things to break. At the same time, exposing unnecessary information can also increase the maintenance costs of your software.
We should actively be trying to hide as much information as we can across service boundaries. That said, this principle isn’t unique to service boundaries — it applies within a single service too — it’s just that the consequences tend to be more severe across services.